GPU Seam Carving
GPU Seam Carving
Content-aware image resizing in CUDA. Seam carving shrinks an image by repeatedly removing vertical seams, connected top-to-bottom paths of low-energy pixels, so flat regions disappear before important detail does.
Overview
This project implements content-aware image resizing using the seam carving algorithm on NVIDIA GPUs. The entire carve pipeline runs on the GPU with no per-seam copy back to the host. Each algorithmic stage has several kernel variants, all validated against a CPU reference and profiled with Nsight Compute.
Result
| Before | After |
|---|---|
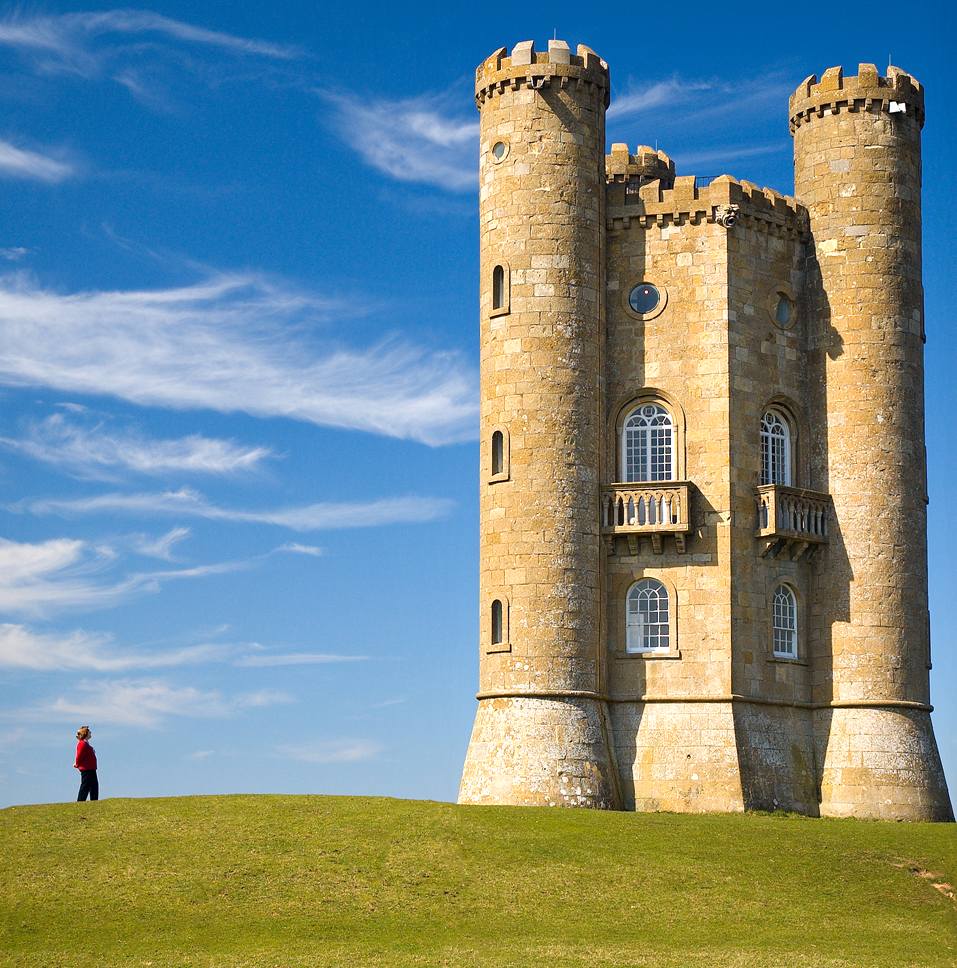 | 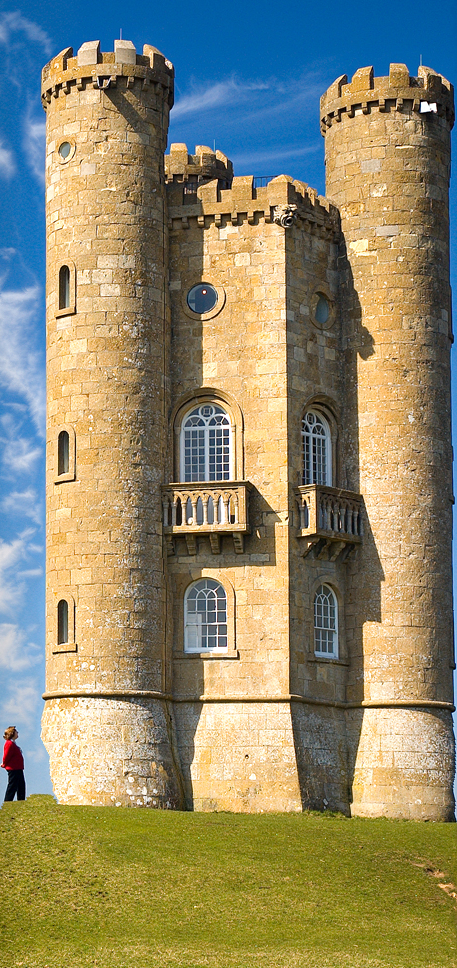 |
How It Works
The algorithm runs in four stages, all on-device:
- Energy — Per-pixel gradient magnitude. High where color changes sharply (edges, detail), low in smooth regions.
- Cumulative Energy — Dynamic programming from top to bottom: each cell is its own energy plus the cheapest of its three parents in the row above.
- Backtrack — Start at the minimum of the bottom row and walk up, picking the cheapest parent each step, to recover the seam.
- Removal — Shift every row left past the removed column, reducing width by 1.
Implementation Highlights
- Multiple kernel variants for each stage to compare approaches
- Grid-stride loops for work distribution
- Cooperative kernels using
grid.sync()for efficient row-wise barriers in DP - Validated against CPU reference — energy, cumulative maps, seam, and output image all compared
- Profiled with Nsight Compute — memory throughput and compute metrics analyzed
Performance Results
Benchmarks run on RGBA input with Nsight Compute profiling (% of hardware peak):
| Kernel | Duration | Memory % | Compute % | Registers |
|---|---|---|---|---|
| energy v1 | 0.04 ms | 76.1 | 76.1 | 37 |
| energy v2 | 0.03 ms | 77.6 | 53.2 | 18 |
| energy v3 | 0.03 ms | 64.4 | 65.4 | 22 |
| DP v2 (cooperative) | 1.2 ms | 1.7 | 0.7 | 20 |
| seam removal | 0.04 ms | 57.8 | 36.3 | 26 |
Key insight: Energy is memory-bound. Loading each pixel as uchar4 instead of byte-by-byte improves throughput and reduces register pressure, yielding a significant win in v2.